

PRODUCT RELEASE • JULY – AUGUST 2026
The critical question you're already asking about agentic AI is whether the data means what the agent thinks it means. "Revenue" in Finance and "Revenue" in Sales are not the same column. "Customer" in your CRM and "Customer" in your warehouse may not represent the same entity. Without semantic context, your agents aren't consuming trusted data — they're consuming labeled rows.
You could tolerate that limitation when a human analyst sat between the data and the decision. It is not tolerable when the consumer is an autonomous agent acting on it at scale. If the semantic layer isn't backed by runtime quality enforcement, and if that quality enforcement only runs at discovery time, the trust guarantee is stale before the agent makes its first call.
The core differentiation: Every other platform answers the trust question at discovery time. Acceldata answers it continuously at runtime, during classification, execution, and consumption.
The answer spans both releases and every layer of the trusted data chain. 26.7 and 26.8 deliver:
- Business Glossary gives your data a shared business meaning, connecting canonical terms directly to the technical assets and Data Products that implement them, making your data estate legible to agents and analysts alike.
- Runtime quality enforcement catches what single-column monitoring misses; Multivariate Anomaly Detection, Unified Tagging, and async execution reporting maintain your quality signal continuously, not just at registration.
- Data Products V2 and the Python SDK give you the consumption surface: provenance-backed, access-controlled products and a typed, retrying SDK that puts the full trusted chain in a single access pattern.
01 Business Glossary — The Semantic Layer Agents Actually Need
Business Glossary, introduced in ADOC 26.7, gives your data stewards a centralized place to define the terms that matter and to connect them directly to the technical assets and Data Products that implement them. The glossary is organized as a three-level hierarchy: Glossary, Categories, and Terms. Each term carries a definition, related terms, synonyms, and direct associations to catalog assets and published Data Products. When a business user or an agent searches for "Customer Lifetime Value," they navigate directly to the datasets and products that represent it, without needing to know the underlying table names.
This is the semantic bridge that governance platforms have long promised and rarely delivered. When "Customer" and "Client" are linked rather than duplicated, and "Revenue" has a canonical definition tied to the assets that calculate it, your entire estate becomes legible to anyone consuming it — human or automated. The glossary doesn't just describe your data estate. It interprets it.
But a glossary built on top of stale or silently broken data doesn't solve your trust problem. A term pointing to a table where the underlying column relationships have quietly drifted gives an agent confident access to unreliable data. Semantic completeness is only as trustworthy as the quality layer underneath it.
What's included:
- Three-level hierarchy: Glossary, Categories, and Terms with names, acronyms, definitions, and descriptions
- Term relationships: Parent/child hierarchies, related terms, and synonyms — linked, not duplicated
- Direct asset and Data Product associations: Navigate from a business term to the technical assets and products that implement it
- Steward workflows: Create, organize, and manage terms with role-based ownership
02 Runtime Quality — The Foundation the Semantic Layer Sits On
Most governance platforms solve for discovery time. Your data gets catalogued, classified, and stamped as trusted — once. What happens between crawls, between pipeline runs, between the moment data is registered and the moment it is consumed, falls outside the trust boundary. ADOC 26.8.0 closes that gap: quality enforcement that operates continuously at runtime, not just at registration.
The centrepiece is Multivariate Anomaly Detection. Using an Isolation Forest algorithm, ADOC learns the joint distribution of a selected group of columns over time and flags deviations in their relationships — not just their individual statistics. Take a transactions table where approved_count and total_count should maintain a consistent approval rate: when that ratio silently breaks, no per-column alert fires. Multivariate detection catches it. The failure that looks fine column by column is now visible before it reaches your downstream consumers — or the agents querying them.
Unified Tagging extends that runtime governance to classification. A single key-value tag model — Domain : Finance, Sensitivity : PII — replaces your fragmented labels-and-tags system, with Data Labelers that classify new assets the moment they are discovered during profiling and crawler jobs. A PII column surfacing in a new table gets classified and flagged automatically, before it reaches a Data Product, before an agent queries it. Execution callbacks, previously delivered via synchronous HTTP, now route through a Kafka-based async pipeline, so false job failure signals no longer pollute your quality record when the Control Plane is under load.
What's included:
- Multivariate Anomaly Detection — Isolation Forest model across column groups, catches ratio breaks and relationship drift invisible to per-column monitoring
- Unified Key-Value Tagging — single tag model across assets, policies, rules, and rulesets with full lifecycle management and background reconciliation
- Auto-classification at discovery — Data Labelers classify new assets during profiling and crawler jobs; PII flagged before it enters a Data Product
- Domain-Restricted Alert Visibility — Alerts page and Home feed scoped to a user's assigned domains and resource groups
- Kafka-based execution callbacks — async job result delivery eliminates false ERRORED status from transient Control Plane load
03 Data Products V2 and the Python SDK — The Consumption Surface
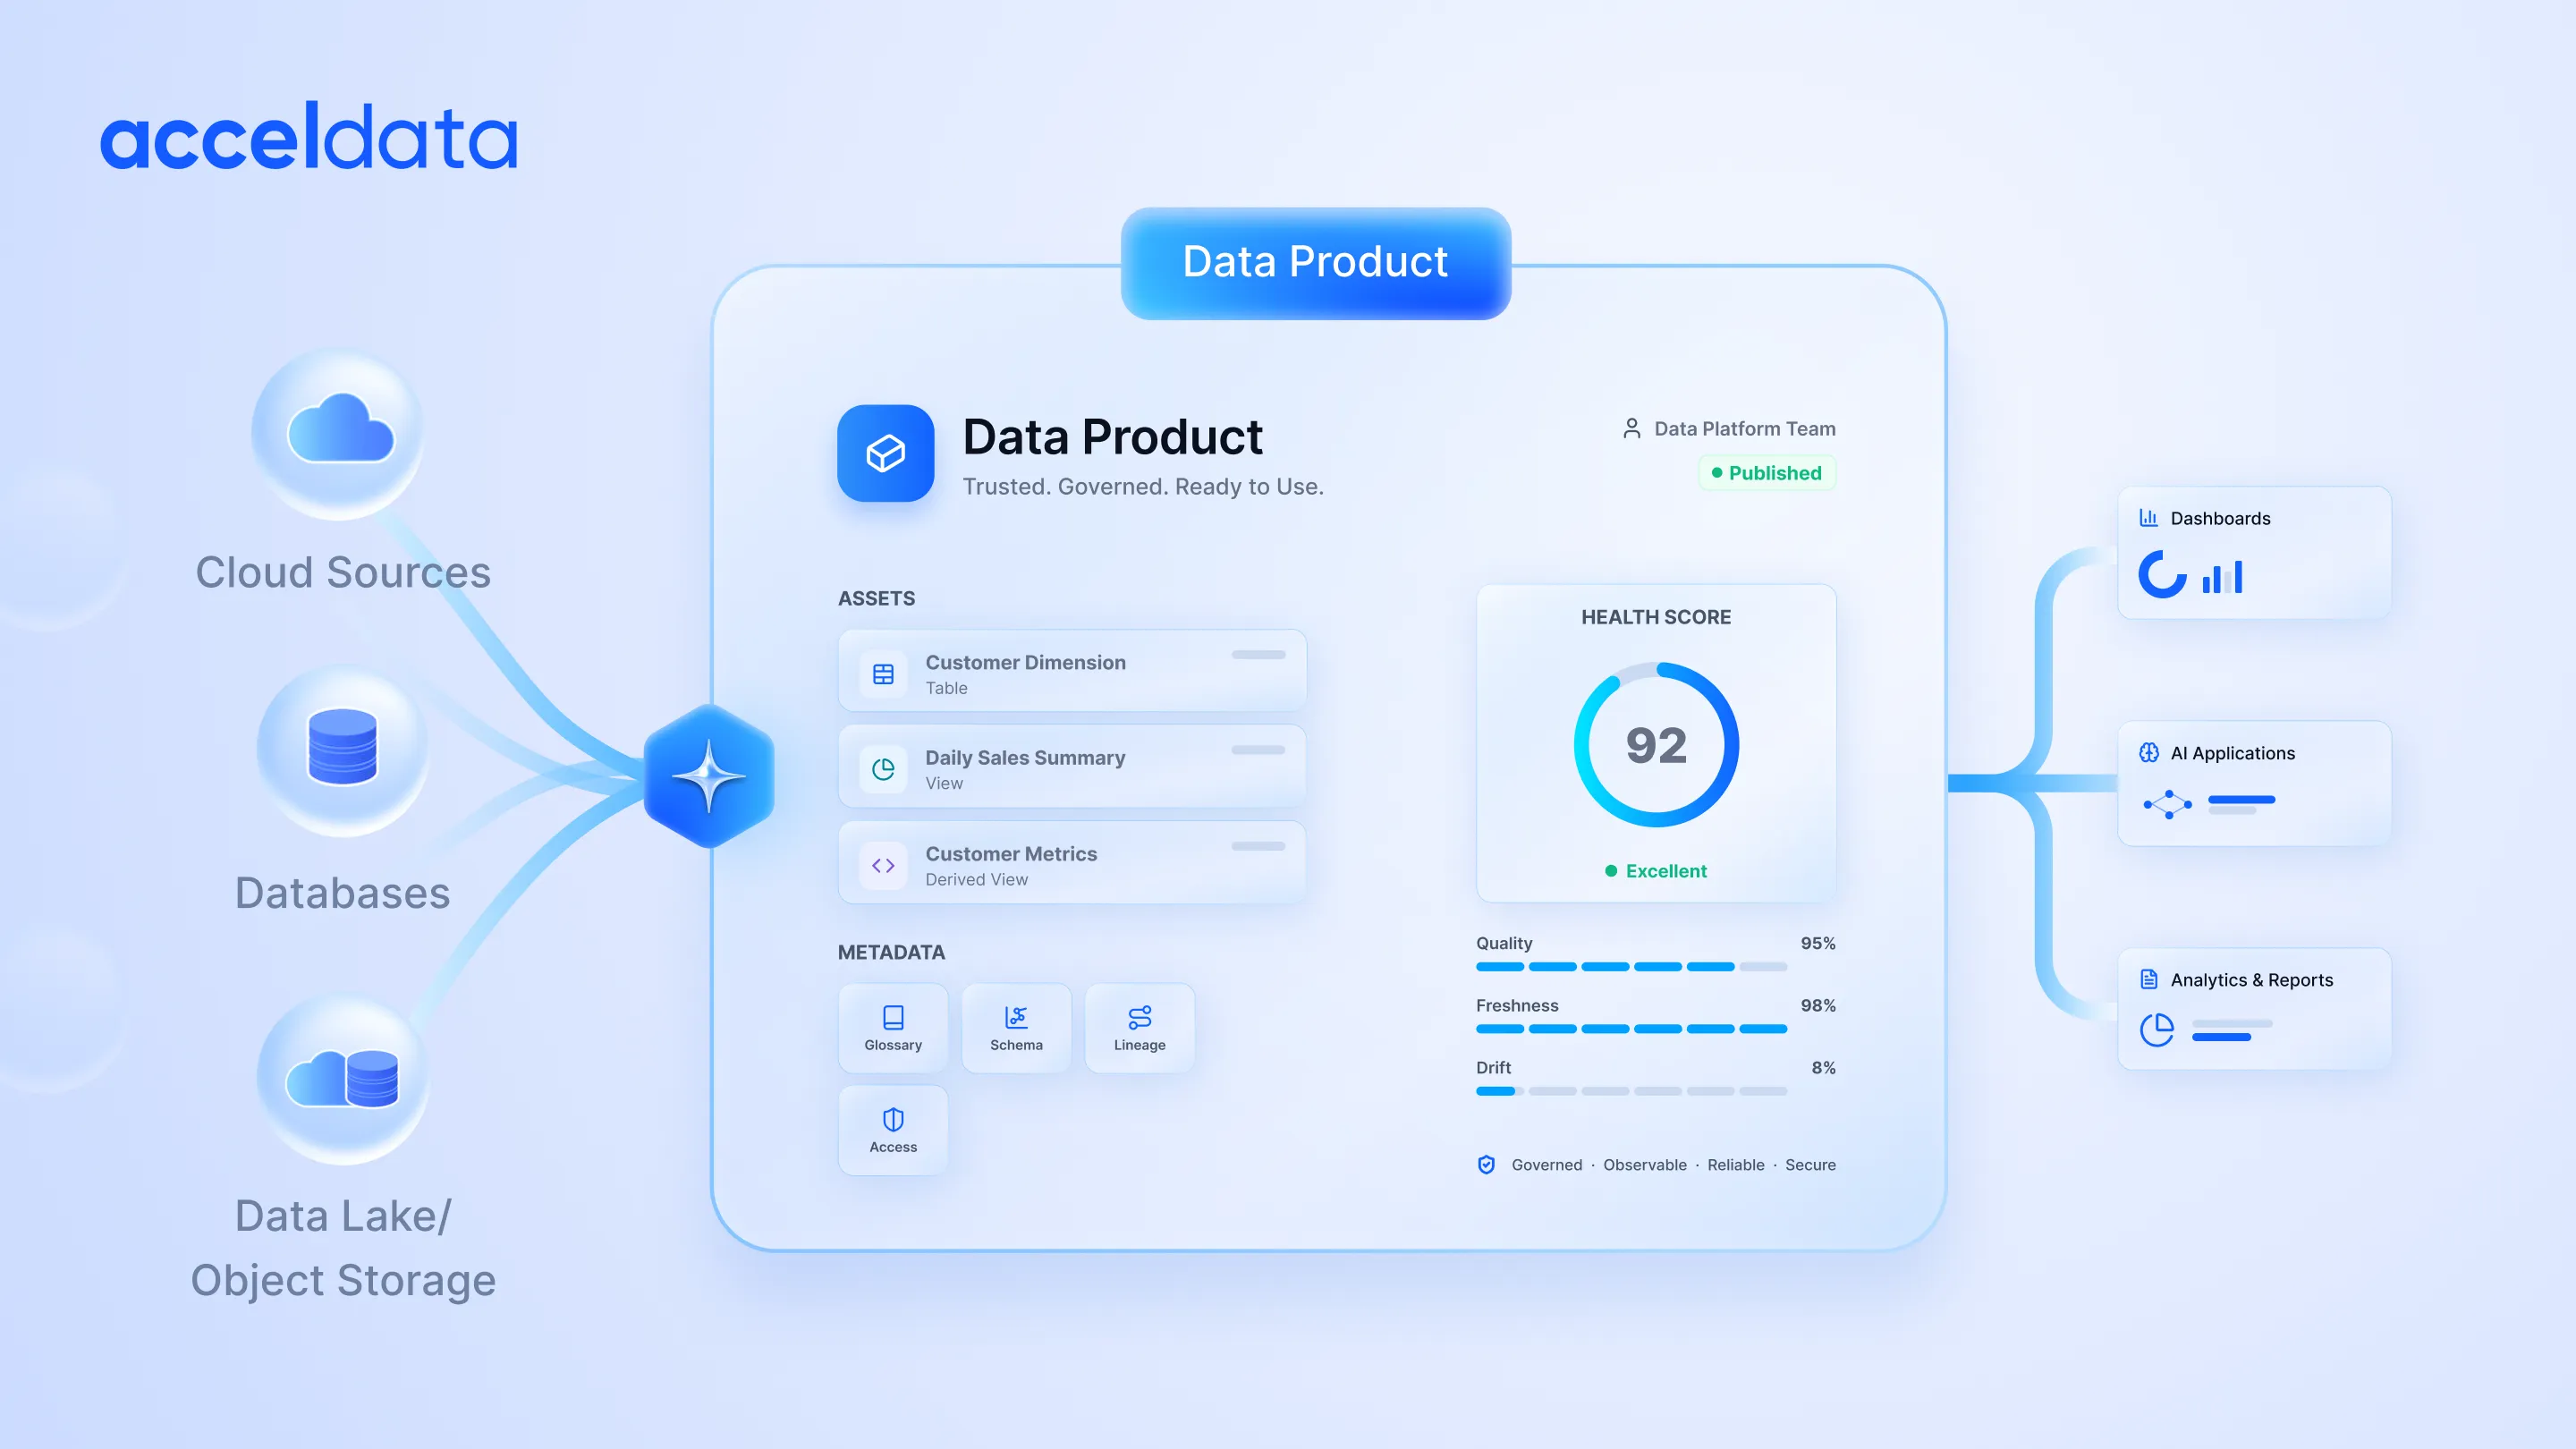
A quality layer and a semantic layer need a packaging layer — a governed unit through which trusted data reaches your consumers. Data Products V2, released in 26.7.0, is that layer. The Marketplace and management interface are now separate: your consumers discover and explore published products in a dedicated read-only experience; your data product owners create and manage in a separate administration view. Modify and Delete permissions are independent, so your governance teams can grant editing rights without granting deletion rights.
Lineage in Data Products V2 now includes data pipelines, Power BI reports, and Tableau reports alongside upstream and downstream data assets. Your consumers — and your agents — can trace how data flows from source through transformation to the BI layer without leaving the product view. The Data Product is no longer just a packaged dataset. It is a provenance-backed, access-controlled unit of trust, connected to the quality layer underneath it and the semantic layer that describes it.
The new acceldata-sdk-python, released as GA in 26.7.0, is the programmatic access layer for everything above it. Generated directly from ADOC's OpenAPI specifications, it gives you Pydantic v2 typed models, resource-oriented APIs, and a built-in retry framework with exponential backoff. Pipeline-to-policy correlation via pipeline_run_id creates end-to-end traceability from execution through data quality result. When your agents consume a Data Product through this SDK, they get the full chain — semantic context, runtime quality assurance, governed packaging — in a single access pattern.
What's included:
- Separate Marketplace and management views — your consumers explore, your owners govern; accidental edits eliminated by design
- Enhanced lineage — pipelines, Power BI, and Tableau reports in the lineage graph with direct navigation to pipeline detail
- Granular permissions — Modify and Delete now independent; grant editing rights without granting deletion rights
- acceldata-sdk-python (GA) — OpenAPI-generated, Pydantic v2, built-in retry with exponential backoff, pipeline-to-policy correlation
- Migration notice — legacy acceldata-sdk enters maintenance mode July 2026; end of support at 26.10.0 in October 2026
In This Release
🔤 Business Glossary — Preview • 26.7.0
Give your data estate a shared business language. Connect canonical terms directly to the technical assets and Data Products that implement them, so your agents and analysts navigate by business meaning, not by table name.
Read the full Business Glossary announcement →
⚡ Runtime Quality Foundation — New • 26.8.0
Catch what single-column monitoring misses. Multivariate Anomaly Detection, Unified Key-Value Tagging, Domain-Restricted Alert Visibility, and async Kafka-based execution callbacks keep your quality signal accurate at runtime — not just at registration.
Read the full Runtime Quality announcement →
📦 Data Products V2 + Python SDK — GA • 26.7.0
Package and deliver trusted data with confidence. A separate Marketplace, enhanced lineage, and granular permissions — consumed through a typed, retrying SDK built so your agents get the full trusted chain in a single access pattern.
Read the full Data Products and SDK announcement →
Across 26.7.0 and 26.8.0, we've delivered a semantic layer that makes your estate legible, a quality foundation that holds the trust guarantee at runtime, and a consumption surface built for agents and analysts alike. The trusted data chain is not a roadmap. It shipped. Reach out to your Acceldata Customer Success contact or visit docs.acceldata.io for setup guides and full release documentation.
Acceldata • Data Observability Platform • acceldata.io • 26.7.0 & 26.8.0 Release • July – August 2026