

PRODUCT UPDATE • ADOC 26.8.0
Every other platform answers the trust question at discovery time. Your data gets catalogued, classified, and stamped as trusted — once. What happens between crawls, between pipeline runs, between the moment data is registered and the moment it is consumed, falls outside the trust boundary. By the time an agent queries that data, the trust guarantee may be hours or days stale.
A semantic layer built on top of stale or silently broken data doesn't solve the trust problem — it papers over it. A term pointing to a table where column relationships have quietly drifted gives an agent confident access to unreliable data. Runtime quality is what keeps that from happening: quality enforcement that operates continuously, catching failures between registration events, not just at them.
How Runtime Quality Works
Multivariate Anomaly Detection learns the joint distribution of a selected column group over a configurable training window and flags deviations in their relationships — not in their individual values. The model trains automatically and updates as new data arrives; no separate ML pipeline required.
Key distinction: A column that stays within its normal range individually can still trigger an anomaly if its relationship to another column in the monitored group has broken. This is the class of failure that per-column monitoring structurally cannot catch — and the class most likely to reach downstream consumers or agents unnoticed.
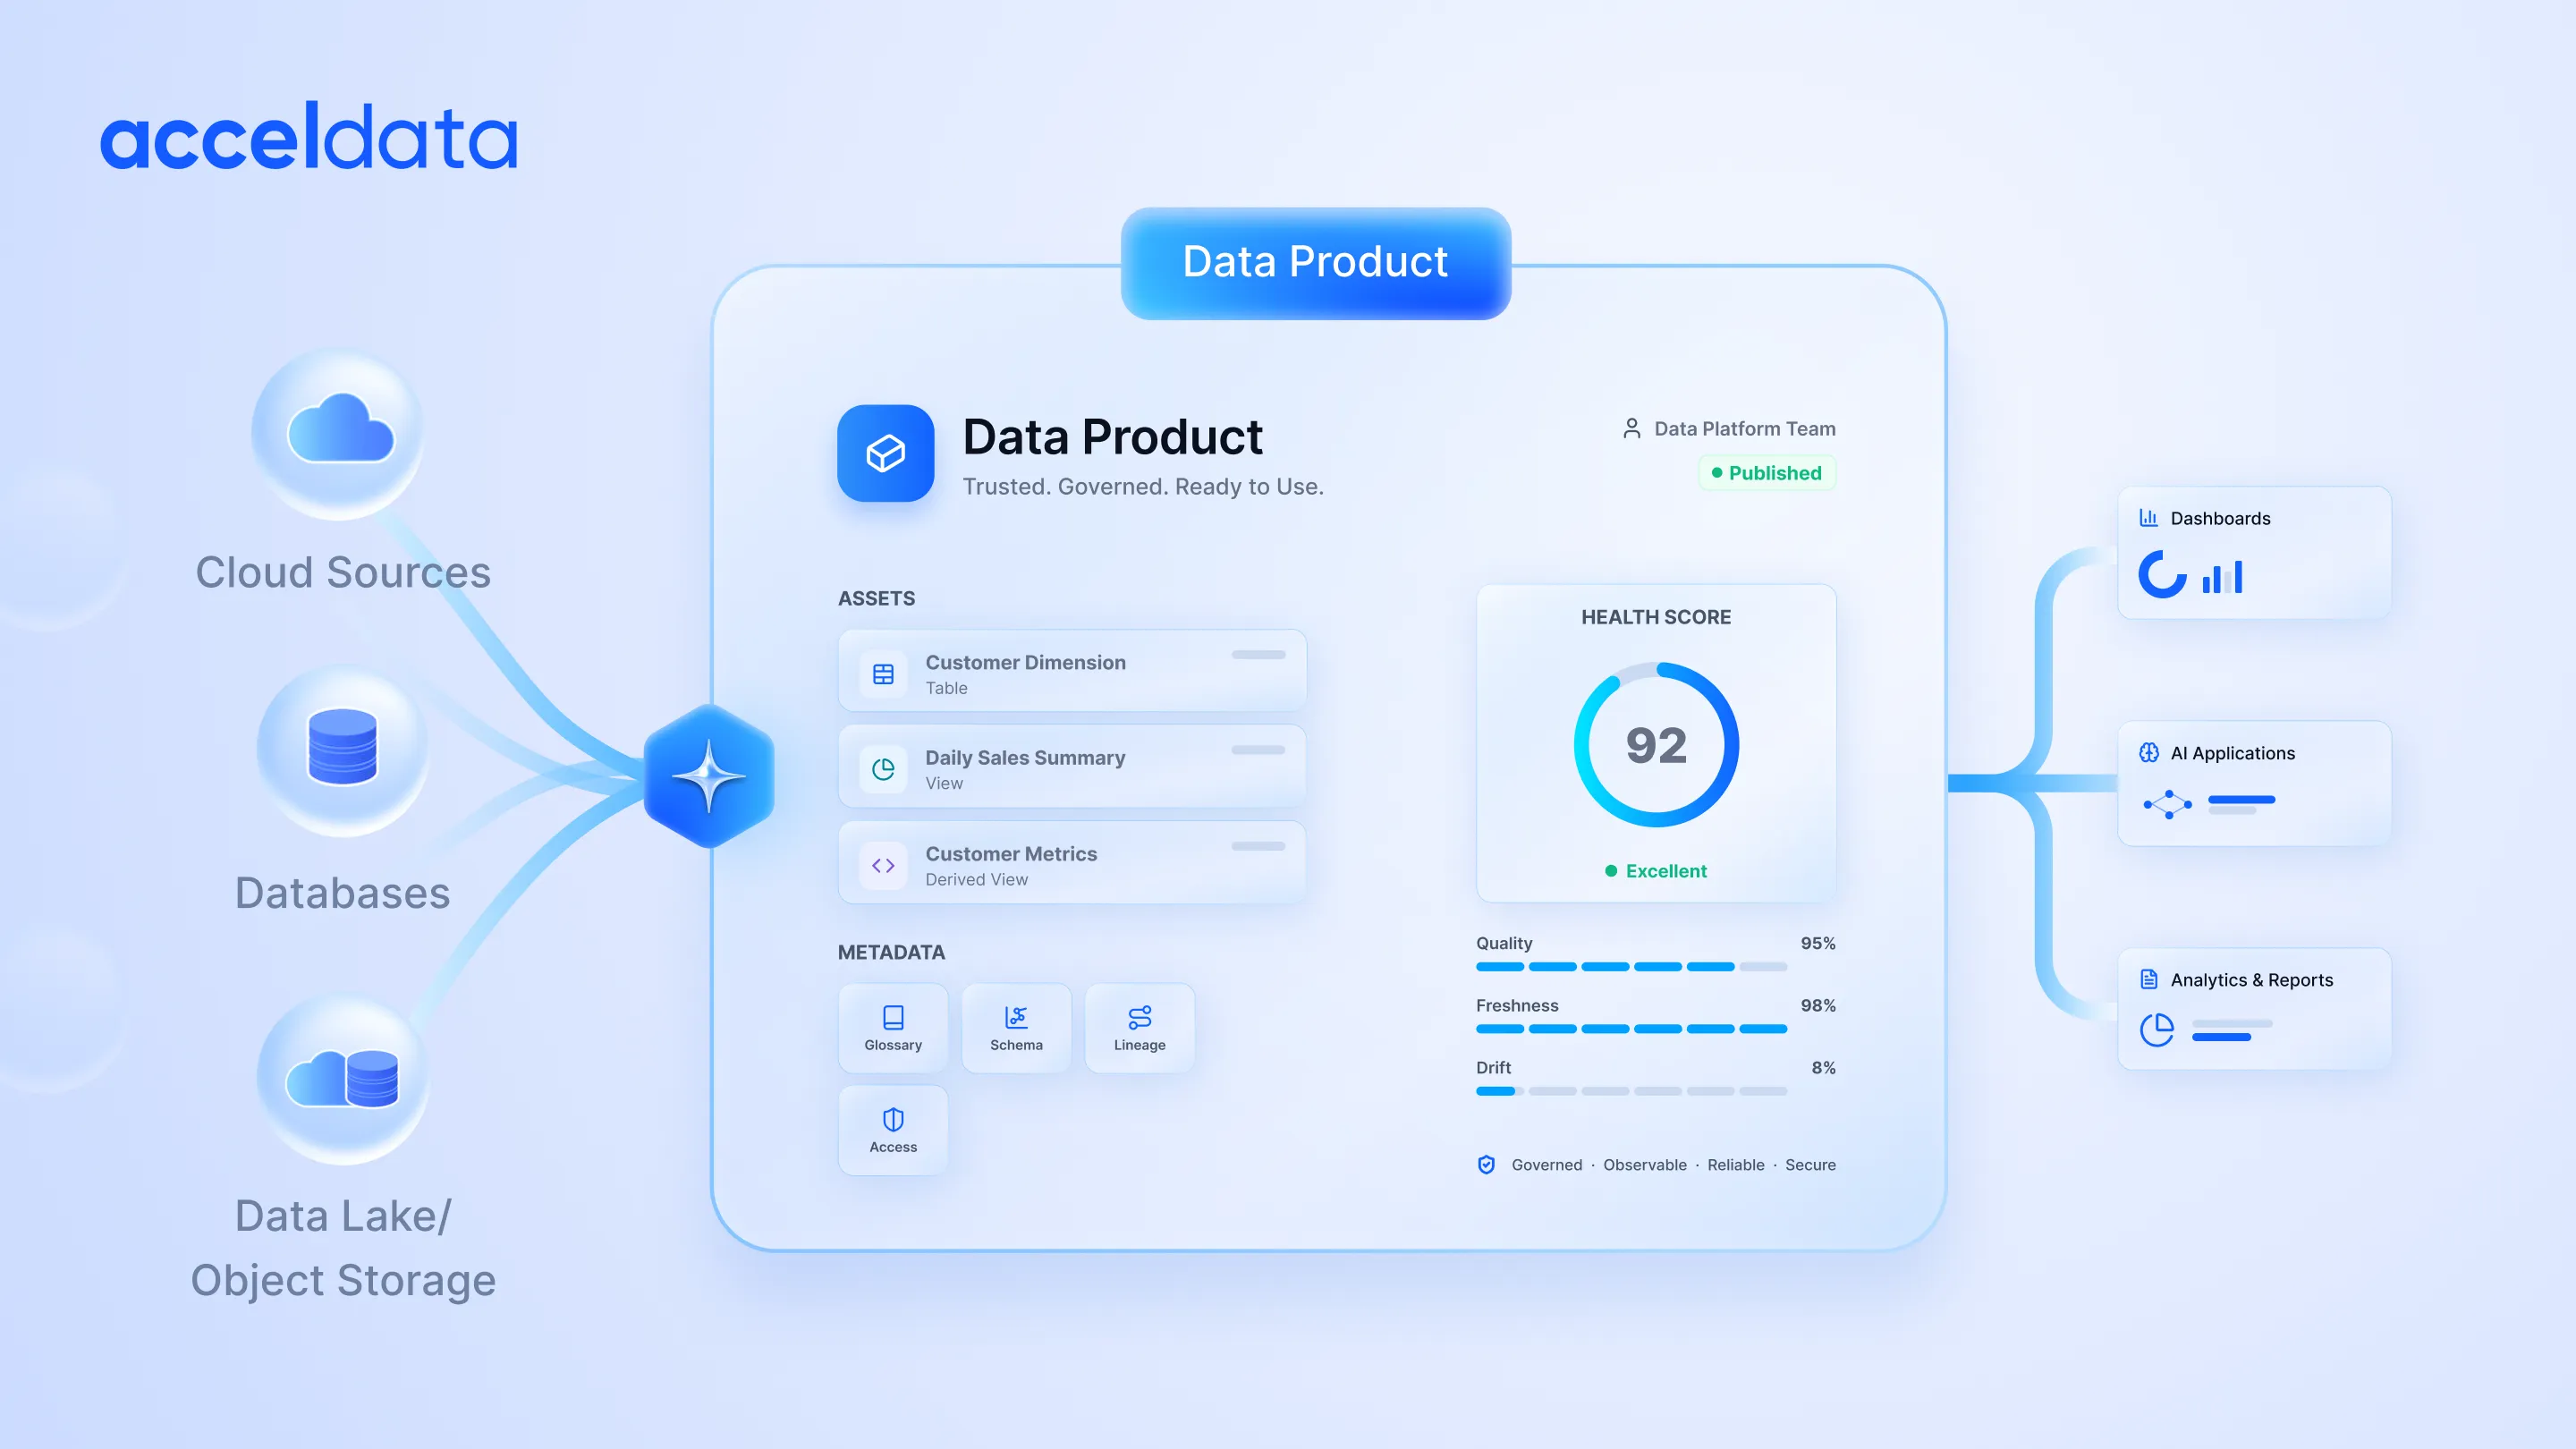
The quality signal that feeds a Data Product's health score is only as accurate as the anomaly detection underneath it. A product built on assets where cross-column relationship drift goes undetected carries a health score that reflects per-column statistics — not the actual reliability of the data as a whole. Multivariate detection closes that gap at the source, before the health score is calculated and before an agent acts on it.
What's New in 26.8.0
Multivariate Anomaly Detection
A multivariate anomaly policy is configured from Governance → Policies → Add Policy → Data Anomaly. You select the column group to monitor, set the training window — the historical period the model learns from — and configure the sensitivity threshold that determines how aggressively deviations are flagged. ADOC handles model training automatically; no separate ML pipeline or model management is required. Alerts route through your existing notification channels: Slack, PagerDuty, email, and webhooks. A single alert fires when the correlated column group shifts, replacing the per-column alert storm that previously accompanied multi-column quality failures.
The practical impact goes beyond catching a new class of failure. Teams running 20 derived columns off a single source metric no longer receive 20 separate univariate alerts when that metric drifts. Root cause analysis starts from one signal, not a queue. Alert fatigue drops. And the quality failures that were previously invisible — the ones that only surfaced in a downstream report days later — are now caught before they leave the source asset.
Unified Key-Value Tagging
Unified Tagging replaces the previous two-system model — where tags (plain strings) and labels (key-value pairs) were managed separately, applied inconsistently, and reconciled manually. The new model is a single key-value system: every tag is a pair (Domain : Finance, Sensitivity : PII), every pair is managed from the central Tags hub under Governance → Tags. Create, retire, merge, and delete tags from one place. Background reconciliation propagates every change across all associated assets, policies, rules, rulesets, and user-defined functions automatically — no manual asset-by-asset remediation.
Data Labelers are the runtime classification layer within Unified Tagging. They are rule-based auto-classifiers that run during profiling and crawler jobs, evaluating new assets against your configured classification rules the moment they are discovered. A column matching a PII pattern gets tagged Sensitivity : PII before it is ever queried, before it appears in a Data Product, before an agent has access to it. Classification is not a post-discovery remediation step — it is part of the discovery event itself.
Key distinction: Data Labeler classification runs at the asset discovery event, not on a separate scheduled scan. The classification latency is bounded by your crawler cadence, not by a secondary process. An asset crawled at 2 AM is classified at 2 AM.
Domain-Restricted Alert Visibility
In a shared ADOC tenant, the Alerts page and Home page alert feed now scope automatically to the data assets within your assigned domains and resource groups. Finance teams see Finance quality incidents. Data Engineering teams see their pipeline alerts. A domain selector appears for users assigned to multiple domains, letting them focus on a specific area without manual filtering. The trust boundary that governs which assets a team can access is now consistent with the alerts they see — enforced by the platform, not by user discipline.
Kafka-Based Execution Callbacks
Job completion callbacks previously used a synchronous HTTP call to the Control Plane. Under load — during high-volume profiling runs, concurrent data quality jobs, or Control Plane deployments — that call could fail, leaving the job stuck in ERRORED state even though the underlying data processing completed successfully. The callback now publishes to a Kafka topic. A consumer service picks it up and applies job-result business logic asynchronously, independently of Control Plane availability. The Dataplane receives an immediate acknowledgement and moves on.
A quality record that shows ERRORED for a job that succeeded is not a minor display issue. It corrupts your audit trail, triggers false incident responses, and — if that job's result feeds into a Data Product health score — produces a trust signal that doesn't reflect what actually ran. The Kafka-based callback means your quality record reflects runtime reality, not the state of the Control Plane at the moment of completion.
What This Looks Like in Practice
Catching a Ratio Break Before It Reaches a Report
A data engineer sets up a multivariate anomaly policy on a financial metrics table, grouping approved_amount, total_amount, and transaction_count. An upstream pipeline bug causes approved_amount to drop while the other two columns remain stable — no per-column threshold is breached, and no univariate alert fires. The multivariate policy detects the shift in the joint distribution and fires a single alert identifying the column group and the point at which the relationship broke. The engineer isolates the pipeline failure before the metrics reach the executive dashboard.
A PII Column Surfaces in a New Table Overnight
A crawler job runs overnight and discovers a new table in a Payments schema. The table contains a column matching the organization's PII classification pattern. Before the data engineering team arrives in the morning, the Data Labeler has tagged the column Sensitivity : PII, it is flagged in the governance dashboard, and it is already scoped out of Data Products that don't have PII access controls configured. The first time a Data Product owner considers adding the table to a product, the classification is already there — not a step they need to initiate.
A High-Volume Quality Run During a Control Plane Update
A platform team rolls out a Control Plane patch during a scheduled maintenance window. Simultaneously, 200 data quality jobs complete across three Dataplanes. Under the previous synchronous callback model, a subset of those completions would surface as ERRORED, requiring manual investigation and re-runs to correct the quality record. With Kafka-based callbacks, every job result is queued and processed regardless of Control Plane availability. The quality record is accurate when the team checks it in the morning — and no health scores were incorrectly penalized.
Who Benefits
- Data engineers — a single alert for cross-column relationship failures instead of per-column alert storms; root cause analysis that starts from one signal, not twenty
- Data platform and infrastructure teams — a quality record that reflects actual job outcomes, not Control Plane availability at the moment of callback; no false ERRORED states to investigate
- Compliance and governance teams — PII and sensitivity classification that happens at discovery, not after manual review; a unified tag lifecycle with full audit logging and background reconciliation
- Data product owners — a health score backed by anomaly detection that catches relationship-level drift, not just individual column outliers
- Domain data stewards — alert visibility scoped automatically to their domain; no manual filtering to see only what's relevant to their remit
Getting Started
- Navigate to Governance → Policies → Add Policy → Data Anomaly to configure your first multivariate anomaly policy. Select the column group to monitor, set the training window, and configure your sensitivity threshold.
- Navigate to Governance → Tags to create your tag library and configure Data Labeler classification rules for the PII and sensitivity patterns relevant to your estate.
- Review domain assignments under Admin → Domains — Domain-Restricted Alert Visibility applies automatically based on existing domain membership; no additional configuration required.
- No configuration is required for Kafka-based execution callbacks — the change applies transparently on upgrade across all existing Dataplane configurations.
For policy configuration details, Data Labeler rule syntax, tag lifecycle management, and Kafka callback architecture, see the Runtime Quality documentation at docs.acceldata.io.